NVIDIA open-sources Snapshot, which saves an initialized GPU inference replica as a checkpoint and restores it, and design partner Crusoe's own test cut time-to-ready from about 8 minutes to 31 seconds.
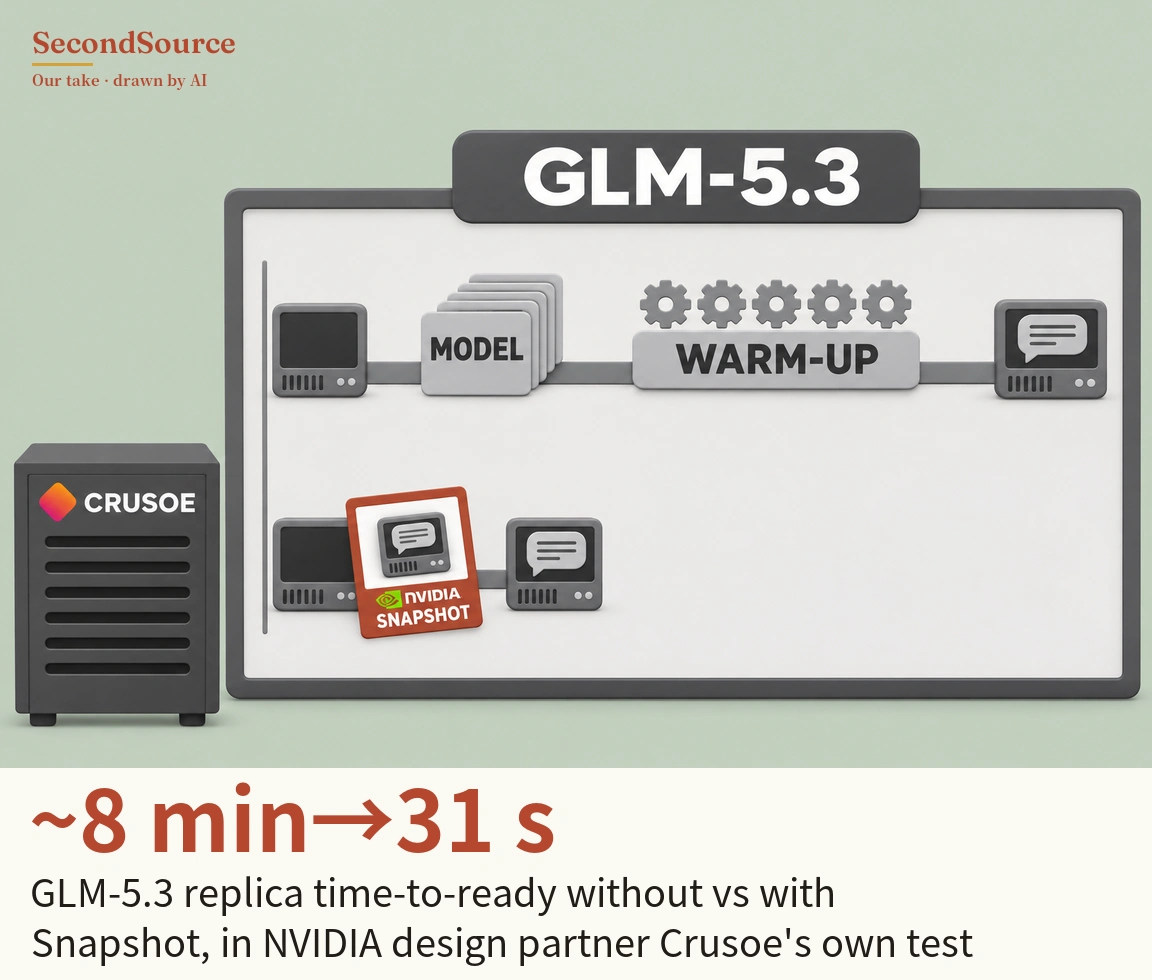
Inference services may be able to keep fewer warm replicas standing by for peaks, but the figures come from NVIDIA's design partners' own tests and no third party has repeated them. Compared with caching only model weights, Snapshot restores a replica that has already finished initializing, and NVIDIA says the model doesn't have to be reloaded or warmed up. Crusoe is a cloud provider that rents out GPUs, and it tested GLM-5.3. Another partner, Saturn Cloud, tested scaling the open-source inference engine vLLM from zero, and startup time fell from 2 to 8.5 minutes to 6 to 34 seconds (NVIDIA, 2026-11-10). How we checked →
Source and checks
This item ran in the brief of Nov 11, 2026, alongside 15 other items. How we checked it, the quote checks and what was still missing that day are on that issue's How we checked page.
Cite this item
SecondSource (2026). "NVIDIA open-sources Snapshot, which saves an initialized GPU inference replica as a checkpoint and restores it, and design partner Crusoe's own test cut time-to-ready from about 8 minutes to 31 seconds.." https://secondsource.io/en/product/2026-11-11-1/. Accessed access date.