Deep Dive Oct 15, 2026
Four chipmakers brought CPU racks for running AI agents to the OCP hardware summit; buyers so far are buying CPU capacity, not racks
Key takeaways
As of October 15, 2026: four companies, AMD, NVIDIA, Intel and Arm, brought CPU racks for agent execution to October's OCP summit, the annual hardware conference of the Open Compute Project. Buyers already buy CPU separately; the largest public case, Meta buying AWS's in-house Graviton5 cores, is a purchase of capacity, and no buyer of a whole rack built for agents is public yet. On this publication's read, near-term share goes to whoever can deliver cores, and only Intel's data supports that so far. The sources checked are vendor press releases and product pages, Intel's 10-Q filing, an arXiv paper, vendor blogs and analyst reports; finding no public buyer there does not mean that no buyer exists.
The bottom line first: four companies, not two, brought CPU racks for agent execution to the same OCP summit. Buyers are already buying CPU separately from GPUs, but what they buy is capacity; no buyer of a whole agent rack is public yet. Near-term share in this layer, on our read, goes to whoever can deliver cores. Only Intel's data supports that reading so far.
OCP, the Open Compute Project, is where the big cloud buyers and hardware makers publish shared open specifications for data-center hardware, and its annual summit is where those specs are unveiled. At the OCP Global Summit on October 12, AMD announced the Helion rack. One Helion configuration holds only CPUs, up to 32,768 cores, and AMD's press release says it is built for hyperscale customers, "providing dedicated capacity for agent execution and connections to separate model inference infrastructure." The same day, NVIDIA contributed its Vera CPU rack specification to OCP. NVIDIA wrote that the rack "is designed to support tool calling, orchestration and sandboxed execution", work split off from the Vera Rubin NVL72 racks that handle training and inference. In the October 13 issue, this publication made a call based on those two announcements. Below, that call is called the original call. It had three sentences:
1. Until now, "agents push up CPU demand" was only a demand story told on Intel's earnings calls; now two rival vendors have turned it into rack-scale products.
2. Buyers will have to split the capacity and power budgets for agent infrastructure into two pools: GPUs for model inference, CPUs for agent execution.
3. The two vendors sell opposite design points, AMD core density and NVIDIA single-thread speed, and whichever wins decides who takes share in this layer.
This piece re-tests each sentence.
First, "two" was the wrong count, and the starting date was too late. At the same OCP summit, Intel showed a Xeon 6+ rack design with more than 46,000 cores in one rack at 133.45 kW, and Arm's AGI CPU systems were already on sale through Supermicro and Verda. Arm commissioned the testing and analysis firm Signal65 to model per-rack workload. That is not an independent test. Four companies treat a CPU rack for agent execution as a product, not two. The line did not start in October either. Arm announced its AGI CPU in March. In April, Meta signed a multi-year, multibillion-dollar deal with AWS for tens of millions of Graviton5 cores, explicitly to run "the CPU-intensive workloads behind agentic AI." NVIDIA unveiled Vera at the end of May, and at the end of September CoreWeave began renting out Vera racks. October 12 was the day the whole industry showed its hand on one stage, not the day this layer began.
Second, on the demand side, buyers already buy CPU separately, and what they buy is capacity. Meta's Graviton5 deal is the largest purchase of CPU for agents in public information so far. Graviton5 is a CPU that AWS designs and offers only on AWS's own cloud, so what Meta bought is compute capacity on AWS. Public information does not say what form the contract takes. At Microsoft's Fairwater campus, a 48 MW CPU and storage building supports a 295 MW GPU cluster, a power ratio of about one to six. That is a single case from SemiAnalysis's on-site reporting, and the 48 MW includes storage, with no split for the CPU share. NVIDIA's first Vera CPU systems went to Anthropic, OpenAI, Oracle Cloud and SpaceXAI, with no quantities published. Helion ships in November. CPUs are already bought as their own line item, but the whole rack built for agents has no public buyer yet.
Third, on the split between core density and single-thread speed, the operating data says each covers a different stretch of the work. DeepSeek's September paper on its sandbox infrastructure is the only public reading of a sandbox fleet so far. The fleet runs on about 160 CPU nodes and 30,000 cores and serves about three million sandboxes a day. About 90 percent of the sandboxes use no more than 5 percent of the CPU capacity they requested, on average, and one node can host 800 microVMs. Those figures come from one company's reinforcement-learning training fleet, and they point toward density and memory. NVIDIA's single-thread argument is about a different stretch: each step of an agent depends on the step before, so the loop only runs fast if each step does. NVIDIA reports, from its own tests, 1.8 times the per-core performance of unnamed x86 CPUs. Perplexity tested its own workflows on Vera. It reports workflows about 1.5 times faster and concurrent sandbox starts up to 1.9 times faster than its current production reference. None of those baselines names a chip model, and no independent test exists. Even NVIDIA's own Vera CPU rack is sold on density: 256 CPUs and 400 TB of memory. The two design points complement each other more than they substitute. On our read, near-term share in this layer depends on who can deliver cores. Intel's second-quarter 10-Q filing shows server unit volume up only 9 percent on the same quarter of 2025 and says "market demand exceeded our available product supply." In the same quarter Intel's average server selling price rose 48 percent year on year, and the filing says most of that came from a richer mix of premium products. Intel's CEO said in September, according to a press report, that Intel can meet only about half of customer CPU demand.
The material for this piece is vendor press releases and product pages, Intel's 10-Q filing, an arXiv paper, vendor and partner blogs, and reporting by analysts including SemiAnalysis, TrendForce and Futurum. Every "none" or "only" below holds within that set.
Why it matters: buyers are already buying the CPUs that agent execution needs as a separate purchase, and they started half a year before the vendors showed purpose-built racks at OCP. Our read is that near-term share in this layer goes to whoever can deliver cores, not to whichever design is better.
What would count as this piece being wrong: if AMD's quarterly earnings press releases still carry no statement of a customer deployment of the CPU-only Helion rack by the end of June 2027, the claim that CPU racks for agent execution are a product layer of their own goes back to being a vendor story.
One: four vendors brought agent-execution CPU racks to the same OCP summit
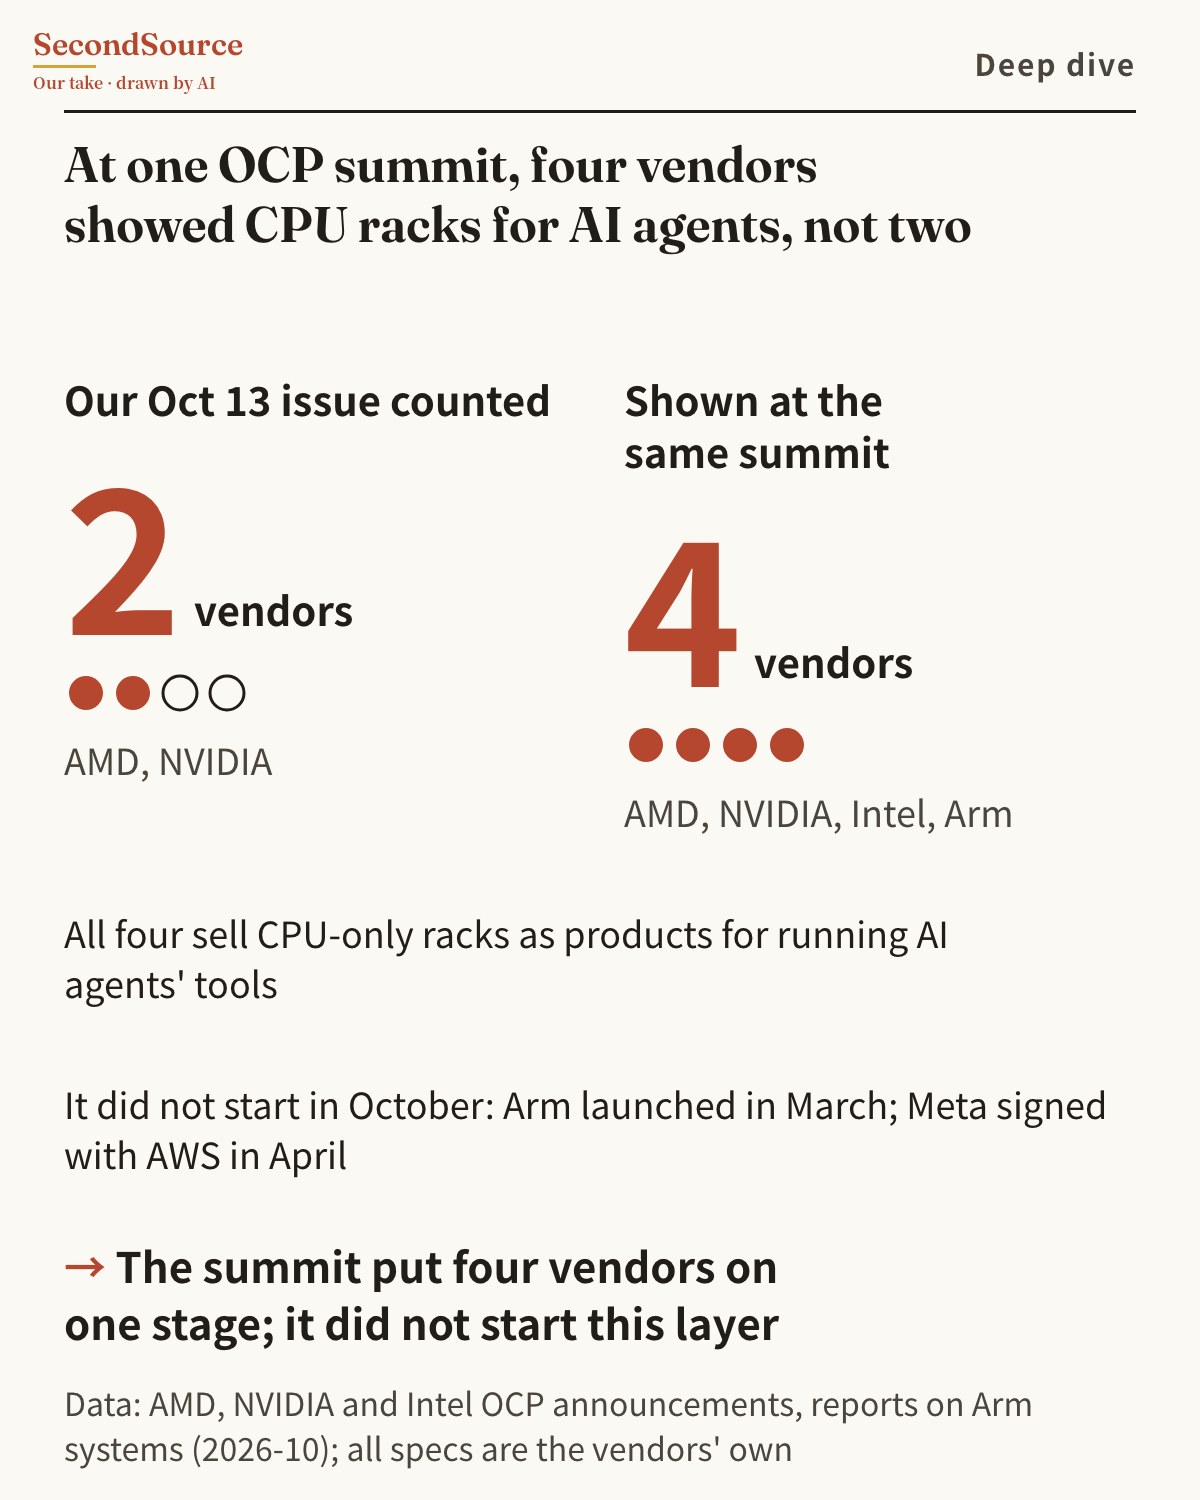
The "two" in the original call were AMD and NVIDIA. Put the announcements of that one week side by side, and there are four.
| Vendor | Product | Per-rack scale (vendor's figures) | Positioning | Timing |
|---|---|---|---|---|
| AMD | Helion CPU-only configuration (6th Gen EPYC) | Up to 32,768 cores | "dedicated capacity for agent execution and connections to separate model inference infrastructure" | Available November 2026 |
| NVIDIA | Vera CPU rack (MGX spec contributed to OCP) | Up to 256 Vera CPUs, 22,528 cores, 400 TB LPDDR5X | "tool calling, orchestration and sandboxed execution", split off from NVL72 | First systems delivered to four customers |
| Intel | Xeon 6+ rack design (ORv3) | "select Xeon 6+ configurations scale beyond 46,000 cores per rack at 133.45 kW total rack power" | "The Intel AI for Enterprise Agent Toolkit is optimized and deployable on Xeon processors today" | On display |
| Arm | AGI CPU systems (Supermicro, Verda and others) | 136 cores per chip; Signal65, commissioned by Arm, puts modeled work per 24 kW rack at 1.99x the EPYC 9755 | Pitched by Arm as agentic AI infrastructure | Systems on sale |
Sources: AMD, NVIDIA blog and Vera rack page, Intel newsroom, Futurum on Arm.
The four also name different buyers. AMD's press release points to hyperscale clouds. NVIDIA's first systems went to frontier labs and Oracle Cloud. Intel is pushing an agent toolkit for enterprises. Arm ships through system builders such as Supermicro and Verda.
The selling points differ, but the headline specs all four publish at the rack level are density figures: cores, power per rack, memory per rack. Those are spec-sheet numbers; they do not mean buyers choose on density. AMD's Helion also offers a high-frequency node, and Arm's per-rack multiple includes single-core performance. The original call cast NVIDIA as the single-thread-speed camp, which is NVIDIA's claim at the chip level. At the rack level, NVIDIA too sells 256 CPUs and 400 TB of memory.
The 6th Gen EPYC is codenamed Venice. AMD also showed its next "agentic CPU," Verano, for the first time. TechTimes reports that the demonstration silicon used "six compute chiplets of 32 cores each" for up to 192 cores, with a 24-channel LPDDR5X memory system at about 2.9 TB/s, and that AMD targets volume production in the first half of 2027. AMD's press release itself gives no Verano specifications. Dan McNamara, who runs AMD's server business, said in the release: "Agentic AI is not a single workload. It spans personal agents, enterprise applications, code execution and complex workflows, each with different compute requirements." Taken at McNamara's word, this layer will not settle on a single design point.
The timeline also starts well before October. Arm announced the AGI CPU on March 24, with Meta as co-development partner. Meta signed with AWS at the end of April. NVIDIA unveiled Vera on May 31 and listed customers "exploring" it: NYSE, Anthropic, OpenAI, SpaceXAI, ByteDance, CoreWeave, Lambda, Nebius, Nscale and OCI. In July Perplexity published its sandbox platform and its Vera test numbers. On September 30 CoreWeave announced Vera racks for rent. At OCP, the four vendors put their versions on the same open-spec platform on the same day. The supply side of this layer had taken shape before then.
Two: buyers already split the pools, but they buy cloud CPU capacity
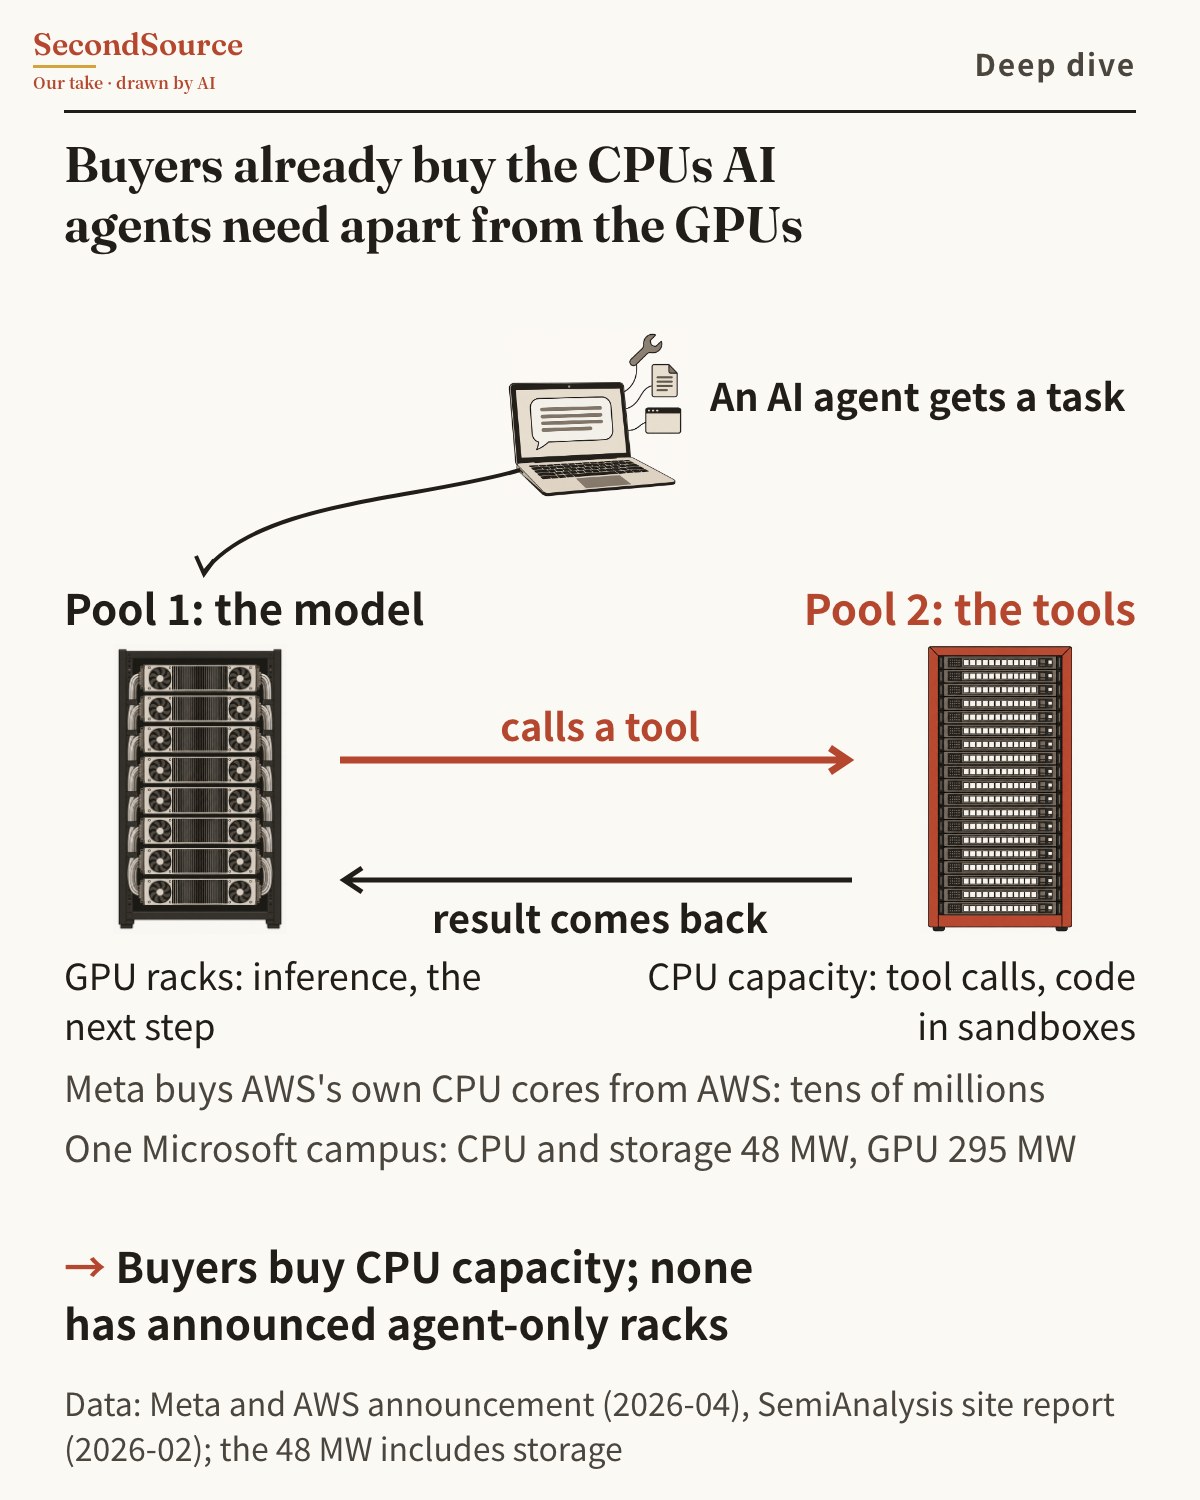
If supply was already there, the next question is whether anyone is buying. The original call set two conditions that would prove it wrong. One: no hyperscale cloud publicly buys CPU-only agent racks before the first half of 2027. Two: the major agent platforms keep sandbox execution in general-purpose cloud CPU pools and buy no dedicated racks. On inspection both hold only in part. CPU purchases have happened; the whole rack as a line item has no public buyer.
Already buying from a separate pool:
- Meta and AWS. At the end of April the two companies announced a multibillion-dollar, multi-year deal under which Meta deploys "tens of millions of Graviton5 processor cores." Santosh Janardhan, Meta's head of infrastructure, said the deal "allows us to run the CPU-intensive workloads behind agentic AI with the performance and efficiency we need at our scale." Amazon CEO Andy Jassy also mentioned the commitment on Amazon's first-quarter call. This is the largest public purchase of CPU for agents to date.
- Microsoft Fairwater. SemiAnalysis's on-site report in February: "Here, a 48MW CPU and storage building supports the main 295MW GPU cluster." That is a power ratio of about one to six. The same report says: "Frontier AI labs are running out of CPUs for their RL Training needs and are scrambling for CPU allocation by competing directly with the cloud providers for commodity x86 CPU servers."
- NVIDIA Vera's first deliveries. A caption on NVIDIA's product page says the first Vera CPU systems went to Anthropic, OpenAI, Oracle Cloud Infrastructure and SpaceXAI. At the end of September CoreWeave announced Vera racks for rent: "Rack-scale Vera at CoreWeave puts 128 CPUs and 11,264 cores in a single rack," supporting "more than 11,000 concurrent environments." CoreWeave described the shape of the load: "A single step in the loop can demand thousands of environments for an hour, then virtually nothing until the next run."
- Perplexity. Perplexity's July sandbox platform post says: "Over the last week, it has supported millions of sandbox creations and tens of millions of sandbox reconnects." Each task runs in its own Firecracker microVM. On October 3 Perplexity's CEO said Perplexity Computer had started deploying on Vera, with the aim of running Perplexity's own sandboxes, optimized for the best silicon.
Not yet happened: no buyer has said publicly that it bought an "agent rack" as a product. What Meta bought is compute capacity on AWS; the Fairwater building is a CPU and storage building. NVIDIA delivered first systems without publishing quantities, and Helion ships only in November. The original call spoke of "separately procured CPU racks." The more accurate phrase is "separately procured CPU capacity." Capacity here means CPU cores and power, rented from a cloud or built in-house, in no particular rack format. The whole rack is one way to package that capacity, and it has no public buyer yet.
The supply structure of this layer mirrors the accelerator layer. Hyperscale clouds first run their own workloads on in-house CPUs such as Graviton, Cobalt and Axion. Merchant chipmakers AMD, Intel, NVIDIA and Arm sell to everyone else. Meta is on both roads: buying Graviton5 capacity from AWS while co-developing Arm's AGI CPU.
Where this sits on this publication's map: this trend was originally about the accelerator layer: training stays on GPUs, while the clouds move their own inference to in-house chips. With agent execution as a new layer, the same dividing line extends one step down. Clouds whose own workloads are fixed and large enough use in-house CPUs; everyone else buys merchant CPUs. The trend's original call is unchanged.
Three: core density or single-thread speed, and the operating data says each covers a different stretch
That leaves the third sentence of the original call, the one about design. The original call left a split open. AMD sells density at 32,768 cores. NVIDIA CEO Jensen Huang argues that the agent loop needs the fastest single-thread CPU, and that CPUs built for the cloud, designed to rent out more cores, point the wrong way. Whichever design point is right was supposed to decide who takes share in this layer. This piece tests the split against two kinds of data.
Actual sandbox-fleet readings lean toward density. On September 19 DeepSeek posted the DSec paper (DeepSeek Elastic Compute) to arXiv. DSec is sandbox infrastructure for training agents at scale. The paper is the only public fleet-level data so far, and the data comes from one company's own reinforcement-learning training fleet. The paper says: "A single production-scale unit of DSec spans around 160 nodes, serving about 3 million sandboxes per day; in production, it supports over 380,000 concurrent sandboxes and sustains over 5,000 sandbox creations per second." The whole platform runs on close to 160 CPU nodes, 30,000 cores and about 250 TB of DRAM. Another reading in the paper: "approximately 90% of both container and microVM sandboxes use no more than 5% of their requested CPU capacity on average." Requested capacity is the CPU allowance each sandbox asks the scheduler for in advance. The paper also reports that one node can host 800 microVMs or 3,200 containers. The nodes are standard two-socket x86 servers with high-core-count AMD EPYC 9655 chips. Our read: this workload is bound by memory and by how many isolated environments fit on a node, not by how fast any one core runs. CoreWeave's "thousands of environments for an hour, then virtually nothing" describes the same shape.
The single-thread argument is about a different stretch. NVIDIA's July post positions Vera as the "max single-threaded CPU at scale." The argument: each step of an agent depends on the result of the previous one, so per-core speed sets how fast the loop advances. More cores cannot shorten a single step. NVIDIA reports that "in loaded CPU workloads that represent agentic execution, Vera delivers 1.8x the sustained per-core performance of x86." Perplexity's own test found "actual Computer-style workflows ran roughly 1.5x faster than our current production reference, and started concurrent sandboxes up to 1.9x faster." CoreWeave says Vera starts agent sandboxes three times as fast as a single x86 CPU. The three companies' numbers do not measure the same thing. The 1.8x is per-core performance, the 1.5x is a whole workflow, and the 1.9x and 3x are sandbox start-up speed. No source breaks down what limits start-up speed, which need not be single-core speed. The three sets of numbers share two more gaps: no baseline names a chip model, and every number comes from the vendor or its partners. AMD, for its part, claims "20% higher performance per core than NVIDIA's 88-core Vera" for Helion's nodes. Brendan Burke of the analyst firm Futurum points out that AMD's July agents-per-watt comparisons "are arithmetic from thread counts and power ratings under a theoretical workload." Both sides are self-reported against different baselines, and neither counts as independent evidence.
Complementary more than substitutes. Burke's judgment after COMPUTEX in June: "The two agentic CPU theses target different points of the agent lifecycle, which means the chips are more likely to prove complementary than substitutable." In Burke's reading, Intel's Xeon 6+ is tuned for density and concurrency in enterprise inference, and NVIDIA's Vera for orchestration speed and tight reinforcement-learning sandbox loops. Our read agrees with Burke's. Confidence in that read is low. Sandbox hosting depends on density, and the DSec readings support that. An agent's tool steps run one after another: each step waits for the previous step's result, extra cores cannot run them in parallel, so per-step latency depends on single-core speed. That half is NVIDIA's argument, and only self-reported numbers support it so far. The two can sit in the same data center. The original call framed it as "whichever wins decides the share." Public operating data shows no buyer making an either-or purchase between the two.
This inference has four limits. DSec covers one company's reinforcement-learning training. Sandbox utilization for production agent products has not been published by anyone. The denominator of "5% of requested capacity" is what was requested, so low utilization may also reflect over-requesting. And no independent test yet compares the two designs on the same workload.
Four: near-term share goes to whoever can ship
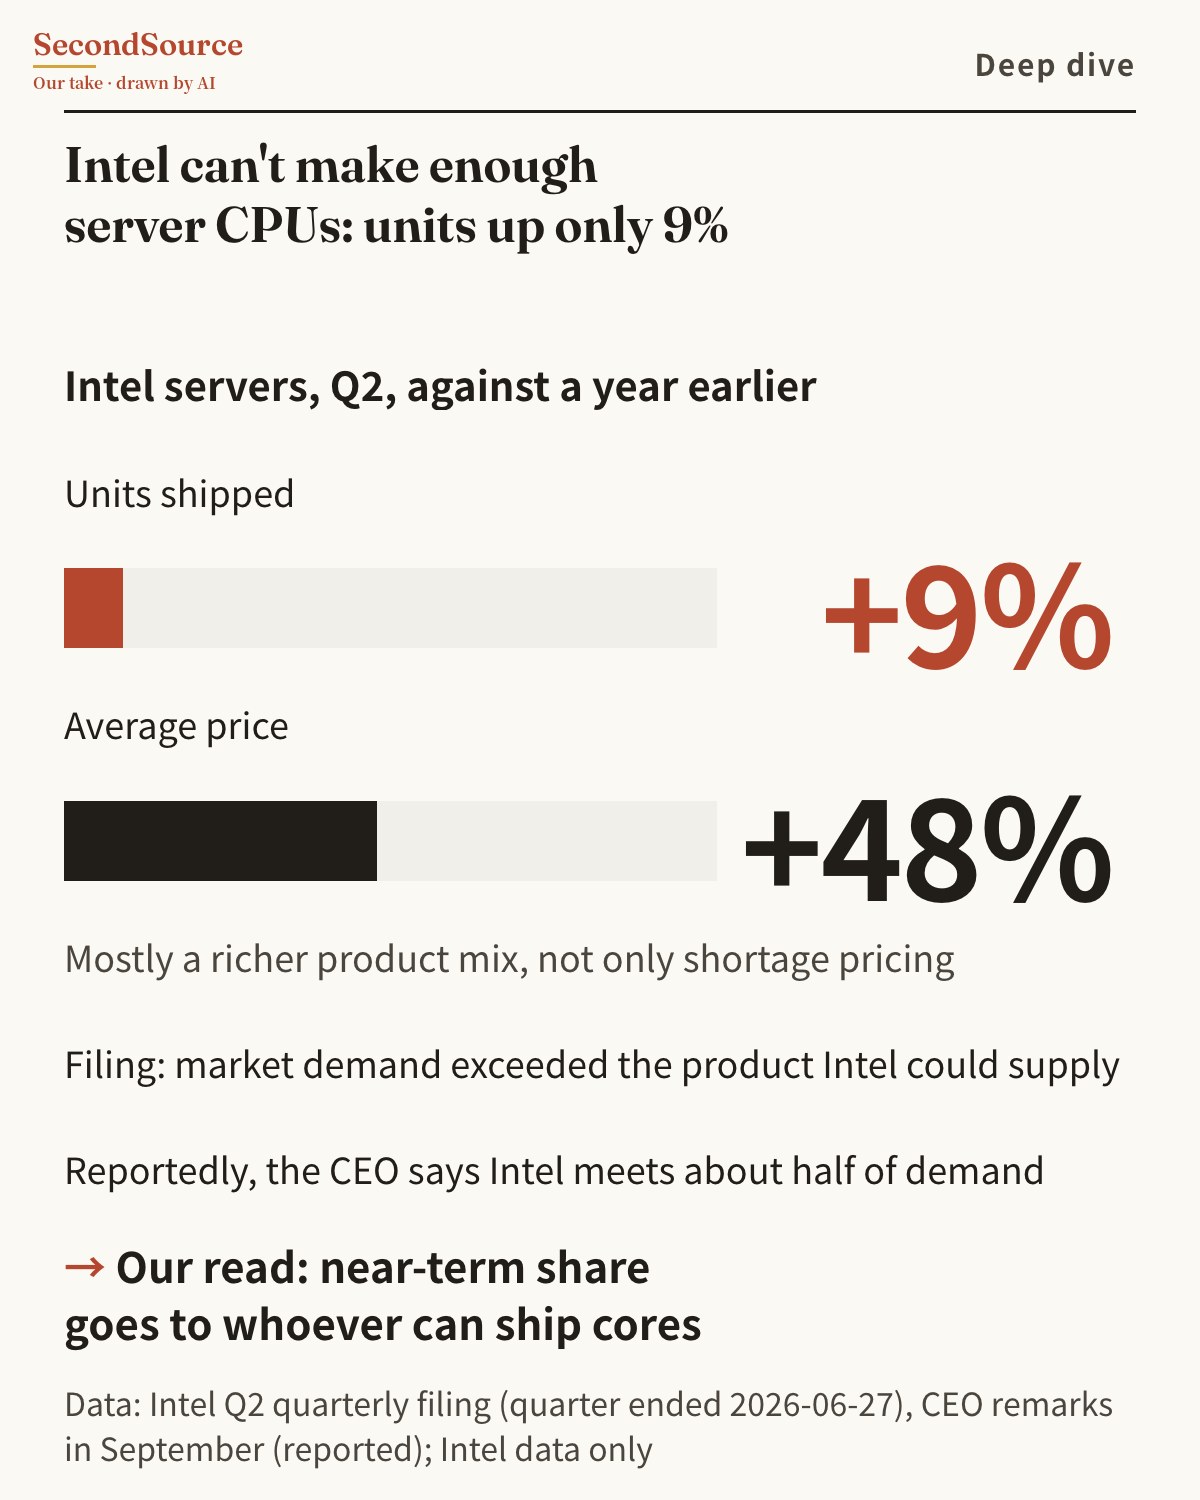
If design is not the variable buyers decide on, what is? For now, the answer is supply.
Intel's second-quarter 10-Q (quarter ended June 27) says server revenue rose "due to ASP increases of 48% and 38%, respectively" for the quarter and the year to date. The filing continues: "The majority of the increase in server ASPs was driven by a higher mix of premium products sold in Q2 2026 and YTD 2026, with demand-based pricing actions contributing to a lesser extent." On volume: "Server volume increased 9% compared to Q2 2025 and 2% compared to YTD 2025, primarily driven by higher hyperscaler demand." And: "Market demand exceeded our available product supply in Q2 2026 and YTD 2026 due to internal supply constraints."
Intel CEO Lip-Bu Tan said in September at Splunk's conference that Intel could meet only about half of customer CPU demand, according to SiliconANGLE. The same report says Intel had already raised its 2026 capital spending to more than US$20 billion. SemiAnalysis wrote in February that "Intel, facing the unexpected depletion of their CPU inventory, is looking to raise prices across their Xeon line." A TrendForce report at the end of September says "Intel and AMD responded by raising prices across select CPU product lines toward the end of 1Q26." The new round of price increases that Taiwanese media reported in October is mainly on Intel's and Qualcomm's PC processors, with AMD reportedly preparing its own. That round is on the PC line, not the server line.
What holds up the supply-bottleneck reading is volume up only 9 percent, together with the 10-Q's statement that demand exceeded available supply. The 48 percent rise in average selling price cannot all be counted as shortage pricing; the 10-Q says most of it came from selling more premium products. AMD has raised its forecast for the 2030 server CPU market to more than US$200 billion, Helion ships in November, and AMD targets volume production of Verano in the first half of 2027. NVIDIA says Vera systems "will be available from system builders and cloud partners starting this fall." Arm's AGI CPU systems are on sale, with no named customer. Our read: from the second half of 2026 through the first half of 2027, whoever has the capacity to ship takes the share. Only Intel's data supports this reading so far. The design contest will have real measurements to compare only around the end of 2027, when AMD's Venice and Verano, NVIDIA's Vera and Intel's Xeon 6+ compete for the same sockets.
Ratio figures have to be read on the same terms. TrendForce writes that "today's AI data centers operate at CPU-to-GPU ratios of roughly 1:4 to 1:8" and that "the future CPU-to-GPU ratio is expected to shift to between 1:1 and 1:2." Arm estimates that CPU cores per gigawatt rise from about 30 million to 120 million. Intel's CEO said in January that the ratio used to be one CPU to eight GPUs, is now one to four, and is heading toward parity or better. All of these are vendor or analyst estimates, and they mix chip counts, power and core counts. The only actual campus case in public data is Fairwater, at a power ratio of about one to six, storage included. That is a power ratio, a different denominator from the chip-count ratios above, so the two cannot be compared directly.
Five: What this changes, and for whom
- Capacity and power planning: Meta and Microsoft have already bought the CPUs for agent execution separately from GPUs; on this point the original call was right. Only two public cases give a sense of scale: Fairwater's power ratio of about one to six, and DSec's 800 microVMs per node. The one-to-one ratios that vendors project for the future are estimates. From the second half of 2026 through the first half of 2027, what limits buying from this pool is lead time.
- CPU vendors: Intel is supply-constrained, with server volume up only 9 percent year on year. Whether rivals are taking share as a result cannot be seen, since first-hand supply-and-demand data from AMD and Arm is not among this piece's sources. At the rack level, all four lead with density specs. The design contest will have real measurements to compare only around the end of 2027.
- Agent platforms and sandbox providers: the economics of sandbox hosting are set by density and memory. In DSec, nine in ten sandboxes use less than 5 percent of their requested CPU capacity, a reading from one company's reinforcement-learning training fleet. The value of single-thread speed concentrates in sequential tool steps and reinforcement-learning loops. Among agent platforms, only Perplexity has said publicly that it is moving sandboxes to Vera, and Perplexity gave no scale.
- Upcoming earnings readings: the agentic CPU story now has four suppliers, not just AMD and NVIDIA. The two nearest readings are the split of server volume and price in Intel's third-quarter results on October 29, and whether AMD's quarterly earnings press releases mention a customer deployment once Helion ships in November.
Our call
CPUs for the agent-execution layer are splitting off from the GPU inference rack and becoming CPU capacity bought on its own. At the OCP summit on October 12, AMD, NVIDIA, Intel and Arm all brought CPU racks for agent execution; this publication's October 13 issue recorded only the first two. The headline specs all four publish at the rack level are density figures. On the demand side, buyers already buy separately. Meta bought tens of millions of Graviton5 cores from AWS. According to SemiAnalysis, Microsoft's Fairwater pairs a 48 MW CPU and storage building with 295 MW of GPUs. Buyers are buying CPU capacity; no one has publicly bought the whole rack built for agents. AMD's Helion ships only in November, and NVIDIA has delivered only the first Vera rack systems. The available data does not support an either-or choice between core density and single-thread speed. DeepSeek's sandbox paper, DSec, covers one company's reinforcement-learning training fleet, where nine in ten sandboxes use less than 5 percent of their requested CPU capacity; that supports density for sandbox hosting. The limit there is memory and how many isolated environments fit on a node, not how fast one core runs. The 5 percent is measured against requested capacity, so over-requesting may account for part of it. On the single-thread side there are only self-reported numbers from vendors or their partners, and no baseline names a chip model. Our call is that the two designs complement each other more than they substitute. From the second half of 2026 through the first half of 2027, share in this layer goes to whoever can deliver cores. The evidence comes from Intel alone: server volume up only 9 percent year on year, a filing that says demand exceeded available supply, and the CEO's reported remark that Intel can meet only about half of demand. In the same quarter Intel's average server selling price rose 48 percent year on year, and the filing says most of that came from a richer mix of premium products.
Readings to watch next
1. Intel's third-quarter results on October 29: the split between server volume and average selling price. If volume growth speeds up clearly, or the filing stops saying demand exceeds supply, the supply bottleneck is easing. If volume growth stays in single digits, section four's call stands.
2. Whether AMD's earnings press releases in coming quarters mention a customer deployment of the CPU-only Helion rack. This is the most direct test of "the agent rack is a real product layer," and it is the first condition below.
3. Any independent test comparing Vera, Venice, Xeon 6+ and the AGI CPU on the same agent workload. Until one appears, every single-thread multiple in section three counts as self-reported.
4. Whether anyone publishes sandbox CPU utilization for production agent products, outside reinforcement-learning training. If it is clearly higher than DSec's reading, section three's "sandbox hosting depends on density" has to narrow.
What would prove this wrong
All three conditions below share a verdict date of June 30, 2027; the date and the thresholds are an observation window this publication set for itself.
1. By the verdict date, AMD's quarterly earnings press releases have never stated that the CPU-only Helion rack was delivered or deployed to any customer. This piece's reading that "the supply-side split is an industry-wide move and a product layer is forming" goes back to "a vendor story," and the original call's first sentence, "agents pushing up CPU demand has become a rack-scale product," is withdrawn together with section one's reading.
2. An independent third party tests the designs on the same agent workload, and the result meets both of these conditions: Vera's per-core or per-step speed is at least 1.5 times that of the comparison CPU, and density-oriented CPUs show no matching advantage in sandbox hosting. Section three's "complementary more than substitutes" fails, and the original call's "the single-thread path wins" is restored.
3. Intel's third- or fourth-quarter results show server volume back to double-digit growth year on year and Intel's filing no longer says demand exceeds available supply, while AMD and Arm also report no shortage. Section four's "near-term share is decided by supply" fails, and design becomes the variable buyers decide on sooner.
Written from the same research and judgments as the Traditional Chinese edition. Sources are linked; we distinguish original documents from reporting and mark what we could not verify.
Sources cited in other language editions
These sources are linked in the body of this piece's other language editions but not in this one.
- stratechery.com/2026/an-interview-with-nvidia-ceo-jensen-huang-about-accelerated
- stratechery.com/2026/intel-earnings-the-agentic-opportunity-intels-mistaken-pess
- stratechery.com/2026/intel-earnings-intels-differentiation-whither-terafab/
- x.com/Beth_Kindig/status/2076377926543515895
- youtube.com/watch
- x.com/jukan05/status/2109474246036791622