NVIDIA argues that inference can scale with almost no added HBM capacity, and its two same-day posts put Rubin at up to 30 times GB300, per dollar in one and per megawatt in the other.
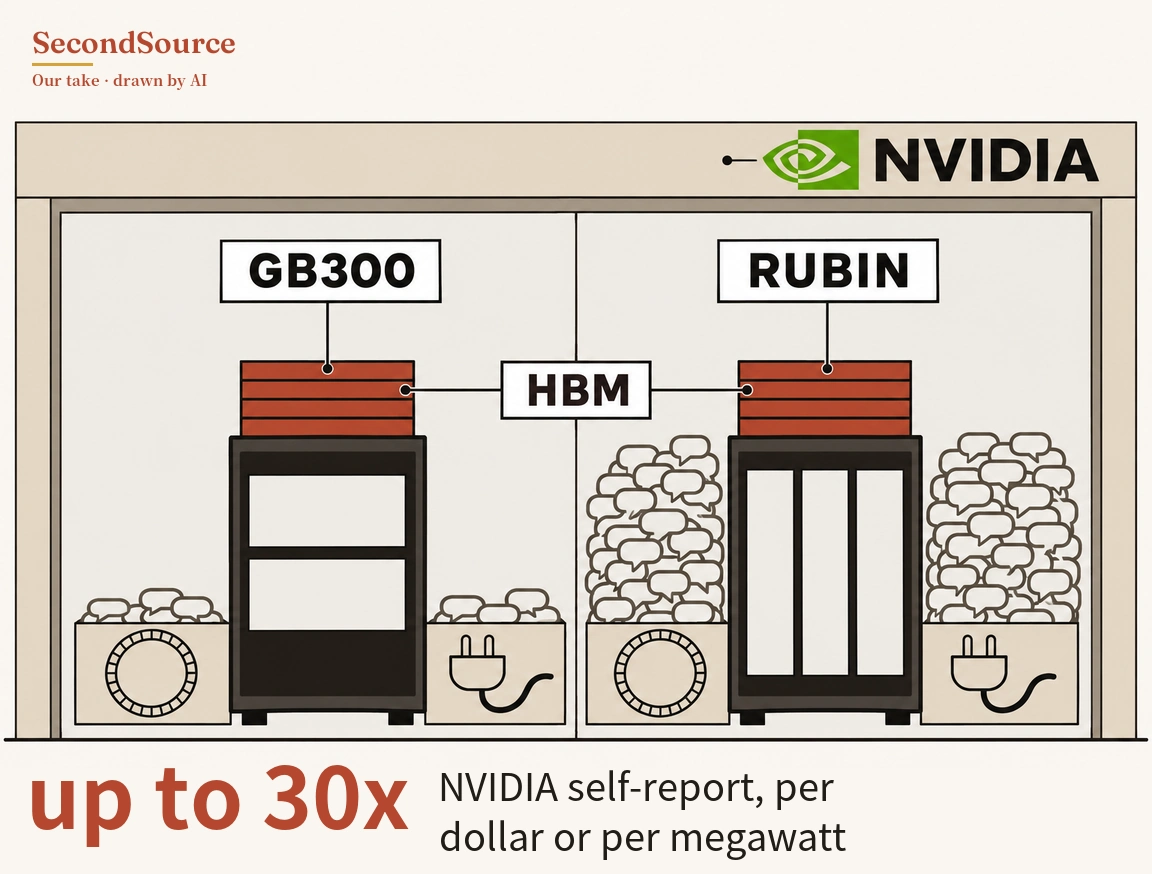
NVIDIA's two same-day posts each self-report Rubin at up to 30 times GB300, one on throughput per dollar and one per megawatt, and the two can't be converted into each other. The general blog puts Vera Rubin NVL72 at up to 30 times the throughput per dollar of GB300 NVL72, at 125 tokens per second per user (NVIDIA, 2026-11-05). The technical blog says up to 30 times per megawatt, at 160 tokens per second (NVIDIA, 2026-11-05). The two posts differ on HBM: the general blog says about 3% more per GPU, and the technical blog says flat at 288 GB from GB300 to Rubin. Rubin also changes the GPU, the interconnect and the CPU, and neither post breaks out how much of the 30 times comes from memory. How we checked →
Source and checks
This item ran in the brief of Nov 6, 2026, alongside 17 other items. How we checked it, the quote checks and what was still missing that day are on that issue's How we checked page.
Cite this item
SecondSource (2026). "NVIDIA argues that inference can scale with almost no added HBM capacity, and its two same-day posts put Rubin at up to 30 times GB300, per dollar in one and per megawatt in the other.." https://secondsource.io/en/news/2026-11-06-5/. Accessed access date.