NVIDIA releases Reshard, a new collective-communication function that makes refit 2.7 to 5.7 times faster on NeMo RL, NVIDIA's reinforcement-learning training framework, in NVIDIA's own tests. Refit is the step that moves new weights to the inference GPUs after each reinforcement-learning step.
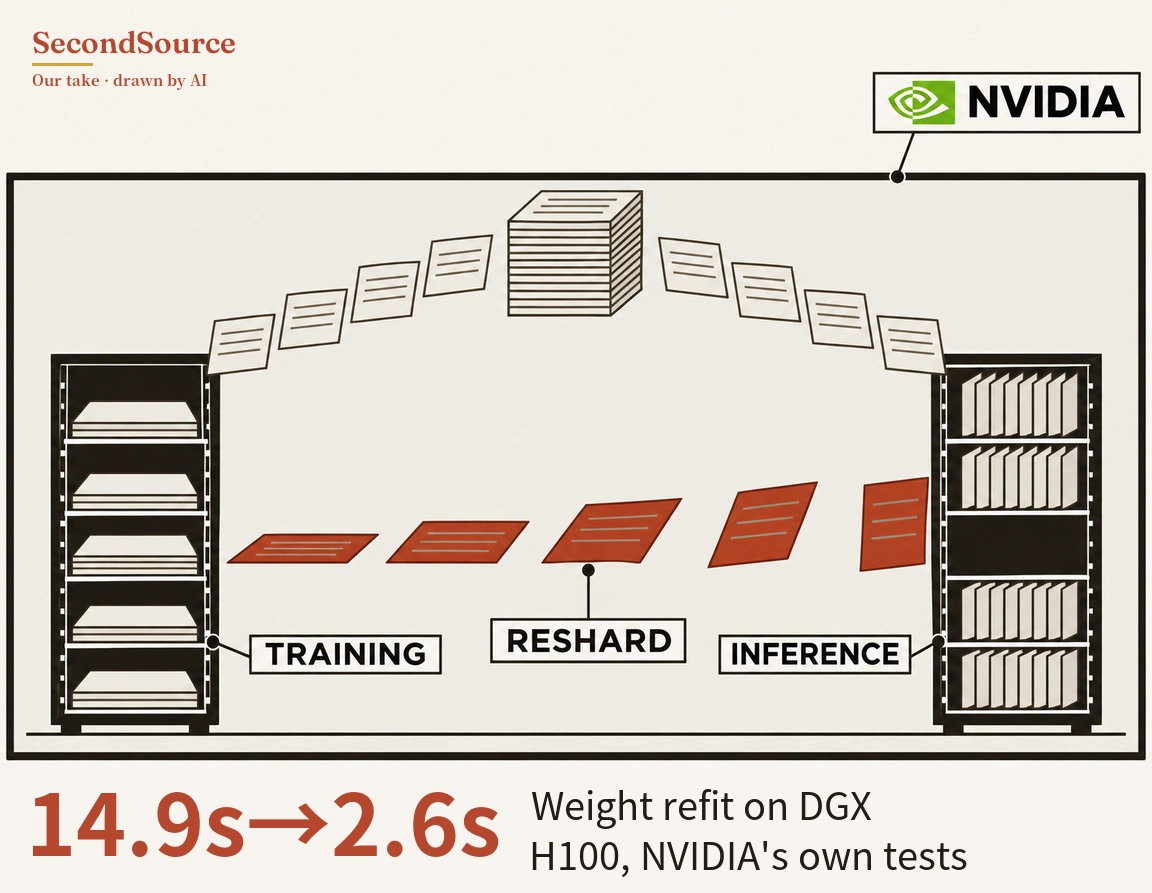
Reinforcement learning on trillion-parameter models is held back by moving weights between training and inference GPUs, and NVIDIA's fix is compared only with NVIDIA's own earlier method. Every few steps the training GPUs must send new weights to inference GPUs that shard the model differently, and NVIDIA writes that for the largest open-weight models each refit moves about 10 TB. Reshard moves tensors straight from the training layout to the inference layout, without first gathering the full parameters and then broadcasting them. In NVIDIA's tests, refit for the 671-billion-parameter DeepSeek V3 fell from 14.9 seconds to 2.6 seconds on DGX H100. On GB200 the same model fell from 6.1 seconds to 2.3 seconds. The two runs use different hardware, so the two speedups aren't the same effect. The first implementation of Reshard sits in NVIDIA's open-source nccl-extensions repository, marked experimental, and NeMo RL currently routes only part of the weights through it. The post doesn't say how much time a full reinforcement-learning run saves (NVIDIA Technical Blog, 2026-11-06). How we checked →
Source and checks
This item ran in the brief of Nov 7, 2026, alongside 13 other items. How we checked it, the quote checks and what was still missing that day are on that issue's How we checked page.
Cite this item
SecondSource (2026). "NVIDIA releases Reshard, a new collective-communication function that makes refit 2.7 to 5.7 times faster on NeMo RL, NVIDIA's reinforcement-learning training framework, in NVIDIA's own tests. Refit is the step that moves new weights to the inference GPUs after each reinforcement-learning step.." https://secondsource.io/en/news/2026-11-07-4/. Accessed access date.