NVIDIA demonstrated the 753-billion-parameter open-weight model GLM-5.3 split across two deskside DGX Station machines; quantized, the model takes about 464 GB, while a single GB300 has only 252 GB of high-bandwidth memory.
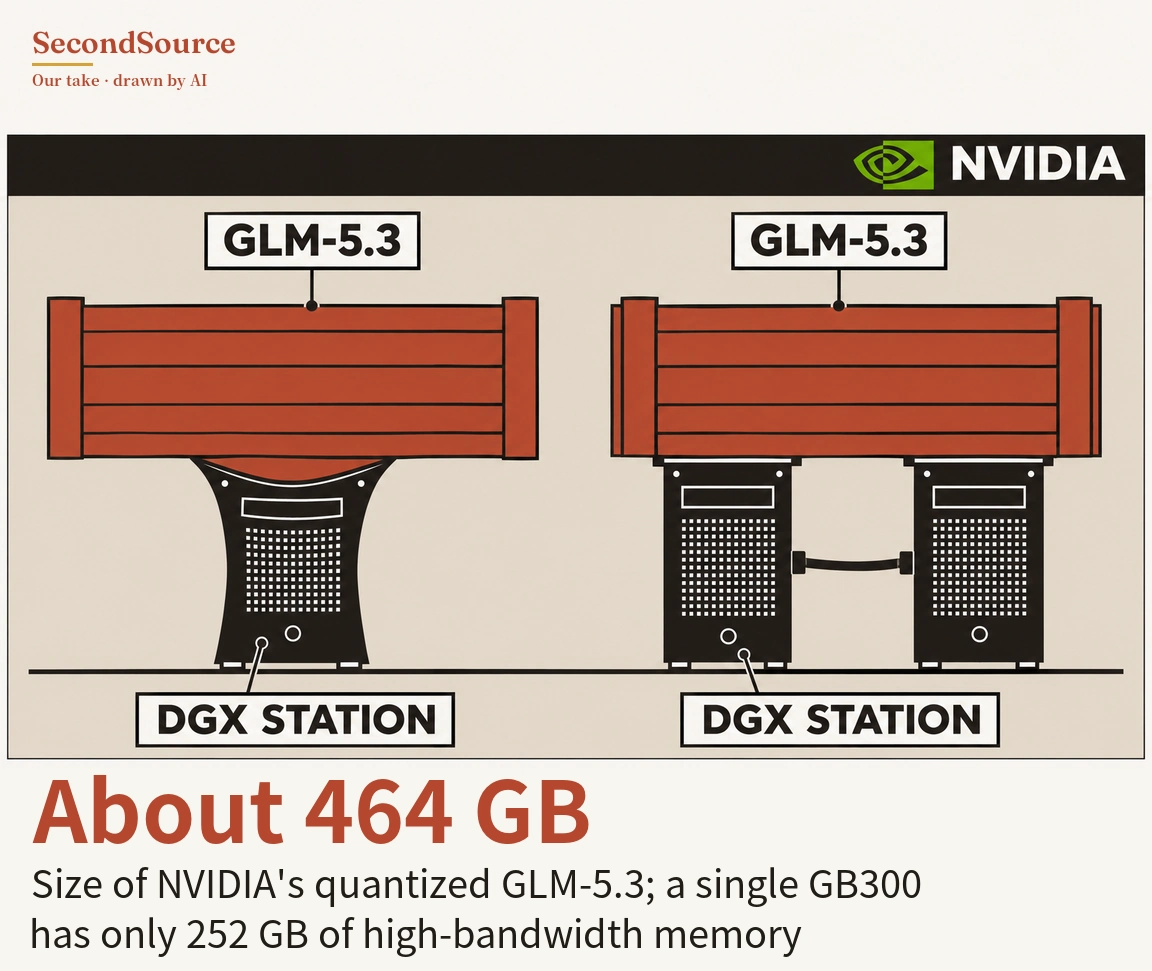
A 753-billion-parameter open-weight model can be served from two deskside machines without the cloud. The performance figures are NVIDIA's own and aren't compared with cloud or single-machine setups. GLM-5.3 is a mixture-of-experts model from the Chinese model company Z.ai, with 40 billion parameters active per token; NVIDIA used its own NVFP4 quantized version. Each machine holds one GB300. The open-source inference server vLLM splits each layer's weights across the two machines, which are linked directly through ConnectX-8 network cards and served through one OpenAI-compatible endpoint. In NVIDIA's own coding-chat test, total throughput peaked at 607.8 tokens per second with 16 concurrent connections, and dropped to 385.0 tokens per second with 32 (NVIDIA Technical Blog, 2026-11-13). How we checked →
Source and checks
This item ran in the brief of Nov 14, 2026, alongside 14 other items. How we checked it, the quote checks and what was still missing that day are on that issue's How we checked page.
Cite this item
SecondSource (2026). "NVIDIA demonstrated the 753-billion-parameter open-weight model GLM-5.3 split across two deskside DGX Station machines; quantized, the model takes about 464 GB, while a single GB300 has only 252 GB of high-bandwidth memory.." https://secondsource.io/en/news/2026-11-14-6/. Accessed access date.