In Perplexity's own test of the medium effort level of its Agent API, the score on the public research benchmarks BrowseComp plus DSQA rose from 55% to 77% while cost fell nearly 90%.
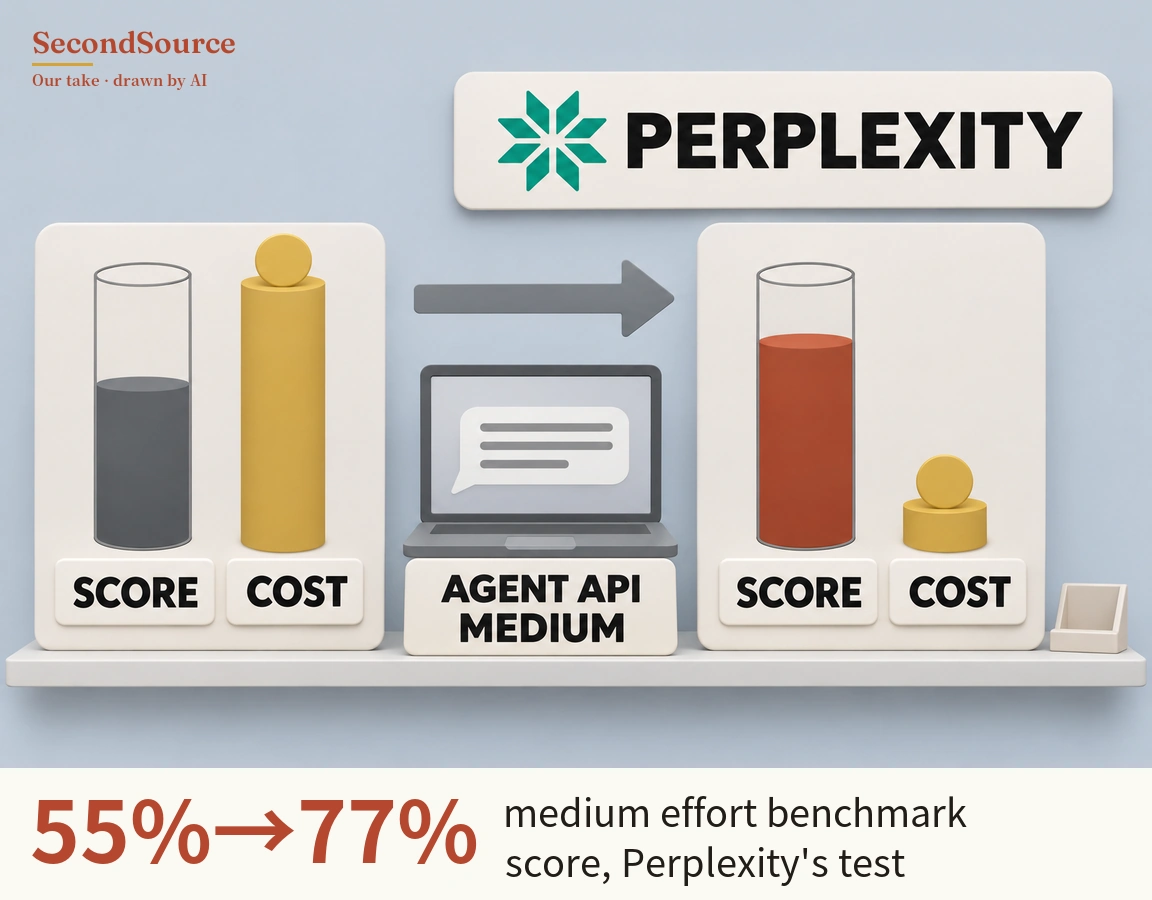
Agent scores and costs swing widely with the step limit, and this is Perplexity's own evaluation with no third-party rerun. The same post raises one model's step limit from 1 to 15, and the score on BrowseComp plus DSQA goes from 41% to 80%. Cost per query rises to about 9 times the original, while the score rises to about 2 times (Perplexity, 2026-11-05). How we checked →
Source and checks
This item ran in the brief of Nov 6, 2026, alongside 17 other items. How we checked it, the quote checks and what was still missing that day are on that issue's How we checked page.
Cite this item
SecondSource (2026). "In Perplexity's own test of the medium effort level of its Agent API, the score on the public research benchmarks BrowseComp plus DSQA rose from 55% to 77% while cost fell nearly 90%.." https://secondsource.io/en/product/2026-11-06-1/. Accessed access date.