Perplexity, the AI search company, launched Orchestrator API, one API for more than 85 models; in its own test, passing Claude Fable 5.2's refusals to an OpenAI model solved 41 of 63 tasks, against 38 for Fable 5.2 alone.
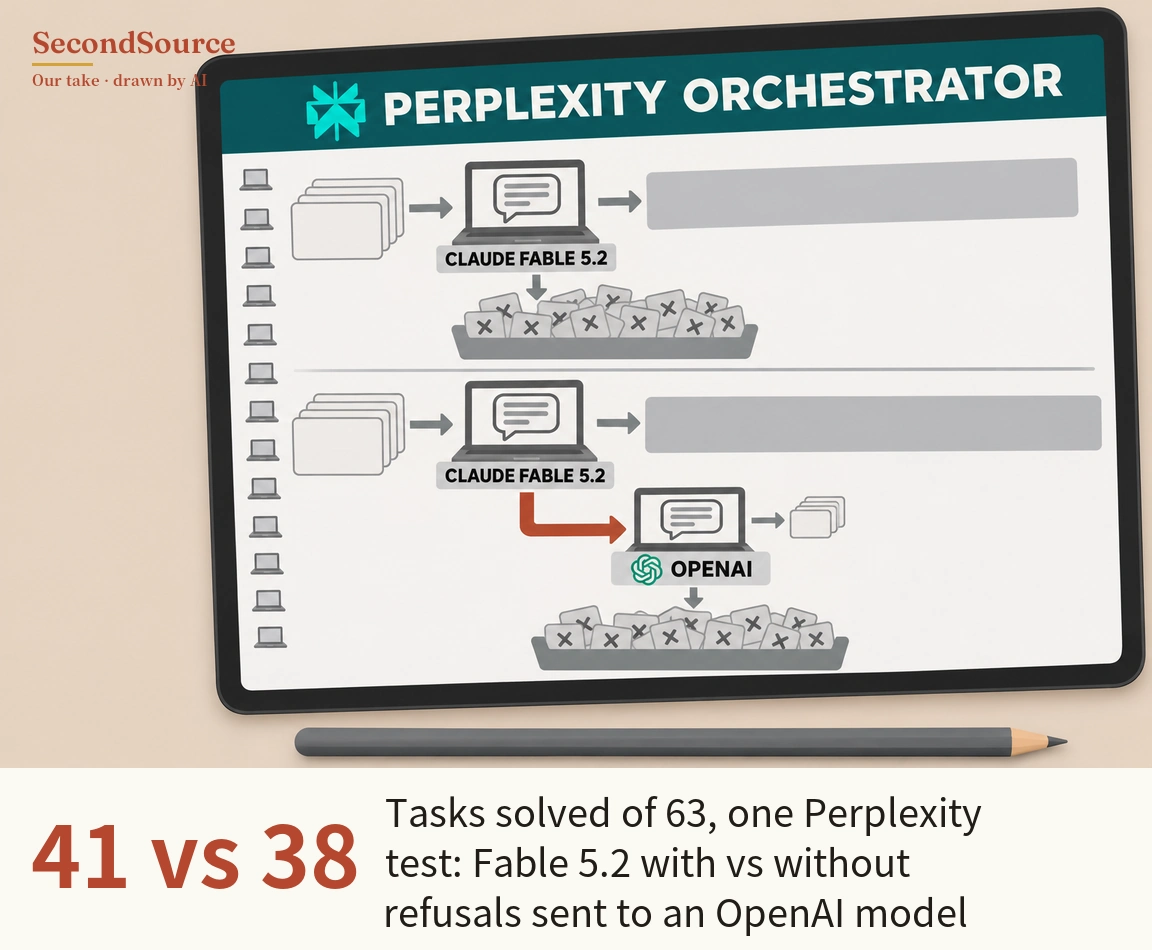
Routing refusals to another vendor's model solved 41 of the 63 tasks instead of 38, but Perplexity ran the test only once, so the gap may be luck, and cost per task was higher. The tasks are a 63-task subset of Terminal-Bench 4.1. When the same model fails at one provider, Orchestrator retries with another provider (Perplexity, 2026-11-17). How we checked →
Source and checks
This item ran in the brief of Nov 18, 2026, alongside 14 other items. How we checked it, the quote checks and what was still missing that day are on that issue's How we checked page.
Cite this item
SecondSource (2026). "Perplexity, the AI search company, launched Orchestrator API, one API for more than 85 models; in its own test, passing Claude Fable 5.2's refusals to an OpenAI model solved 41 of 63 tasks, against 38 for Fable 5.2 alone.." https://secondsource.io/en/product/2026-11-18-2/. Accessed access date.