Research & models Oct 12, 2026
This week · show, October 9
Reflection's RL outspent pretraining; it's self-reported
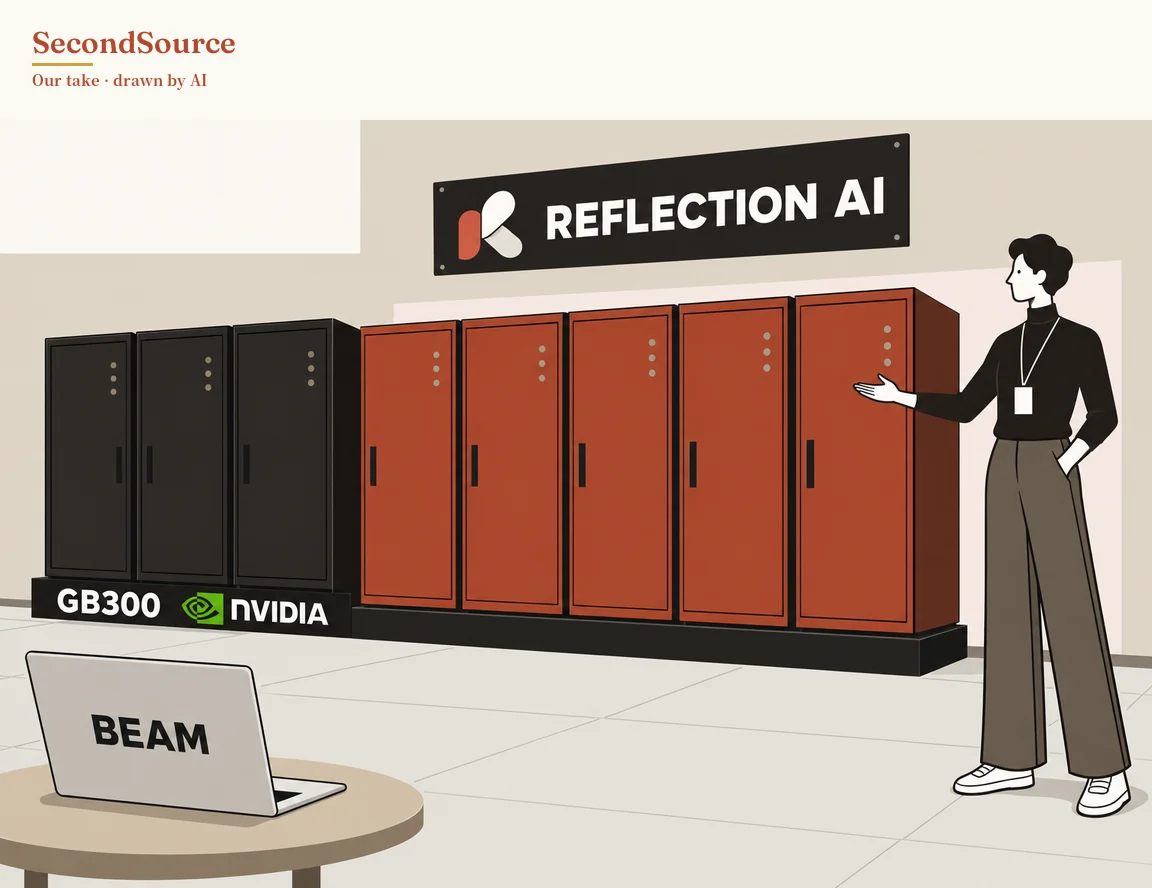
Misha Laskin, CEO of Reflection AI, says pretraining its open model Beam used 6,000 GB300s for several weeks and reinforcement learning used more than 10,000 for four weeks, so more compute went to reinforcement learning than to pretraining. Pretraining has a model read huge amounts of text and learn to predict the next word; reinforcement learning has it attempt tasks and adjusts it with rewards for getting them right. The GB300 is NVIDIA's latest data-center GPU. Beam has 500 billion parameters in total and activates only 23 billion at a time; it's a mixture-of-experts design, meaning it calls on only part of its parameters for each step (No Priors, 2026-10-09). The usual assumption is that pretraining eats the most compute; his account says the opposite, but he doesn't say how much more reinforcement learning used. He also mentioned that pretraining can now finish in about 12 days; that's today's speed, not how long this version actually took. This is the company's own account with no third-party check; another part of Laskin's remarks in the same episode also appears in main-line item 1. How we checked →
Source and checks
This item ran in the brief of Oct 12, 2026, alongside 13 other items. How we checked it, the quote checks and what was still missing that day are on that issue's How we checked page.
Cite this item
SecondSource (2026). "Reflection's RL outspent pretraining; it's self-reported." https://secondsource.io/en/research/2026-10-12-2/. Accessed access date.