Research & models Nov 14, 2026
Anthropic writes that on a self-harm test set, Claude Fable 5.1 responded appropriately 60% of the time when used directly through the API, against 94% in claude.ai with its system prompt.
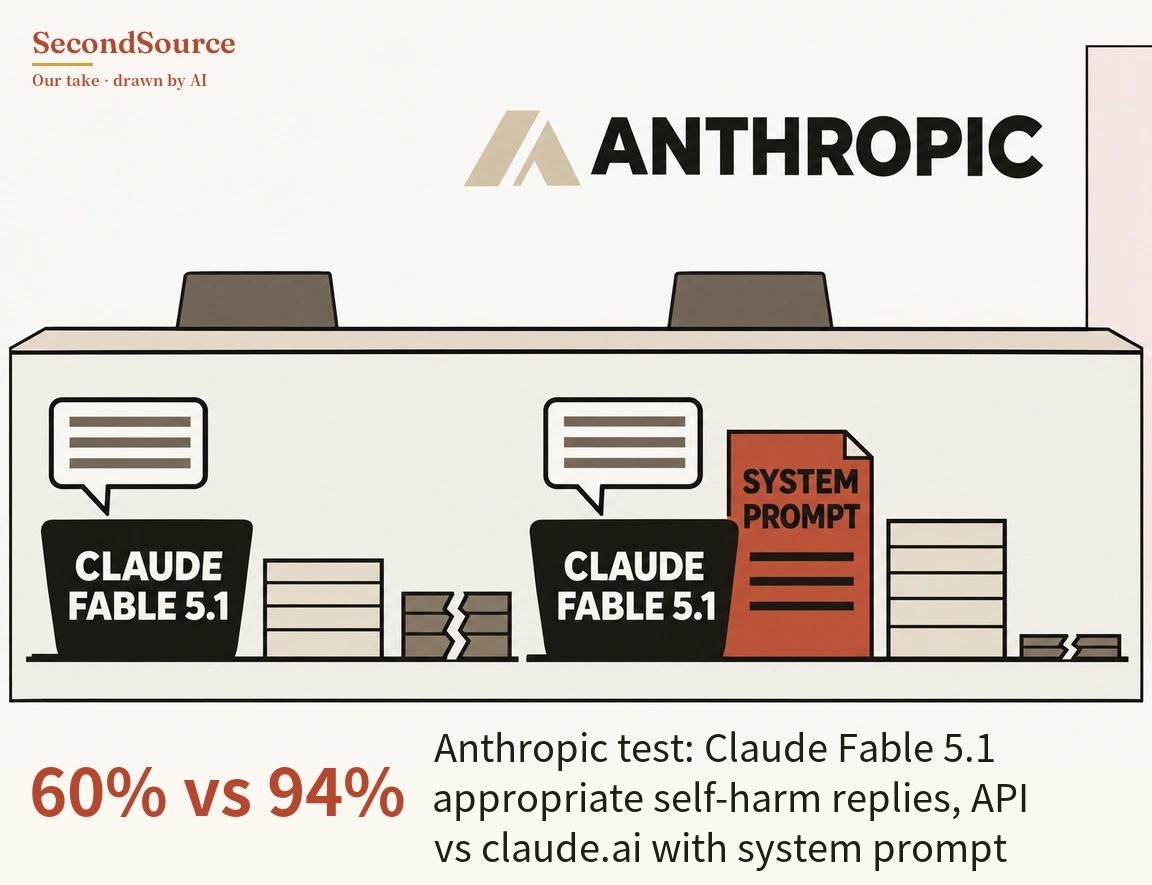
The same model's safety score shifts sharply with deployment settings, so an API score is a poor guide to behavior in claude.ai. Both figures come from Anthropic's own evaluation. Anthropic's November 13 piece on evaluation methods gives another example: Claude Opus 5 and Opus 5.5 scored 98% and 94% on a multi-turn romance-scam evaluation, and Anthropic judges the gap not statistically significant, so neither can be called better. Anthropic recommends at least 100 items for complex multi-turn evaluations and at least 1,000 for simple single-turn ones, and writes that confidence intervals on multi-turn evaluations can exceed plus or minus 10 percentage points (Anthropic, 2026-11-13). How we checked →
Source and checks
This item ran in the brief of Nov 14, 2026, alongside 14 other items. How we checked it, the quote checks and what was still missing that day are on that issue's How we checked page.
Cite this item
SecondSource (2026). "Anthropic writes that on a self-harm test set, Claude Fable 5.1 responded appropriately 60% of the time when used directly through the API, against 94% in claude.ai with its system prompt.." https://secondsource.io/en/research/2026-11-14-3/. Accessed access date.